About OCR PDF
OCR PDF recognizes text from scanned document pages. Select the scanned PDF, set any available language options, run recognition and inspect the export. Compare names, amounts, punctuation, reading order and search results with the scan.
iLikePDF's OCR PDF tool lets you understand scanned versus text PDFs and what this page currently does – free and without any software. It is a good fit for learn how to tell a scan from a text PDF, plan the right workflow before converting a scanned document. You may also know it as ocr pdf online, free ocr pdf.
Everything happens in your browser: your files are not uploaded to our servers. It is private by design, quick to use and mobile-friendly. This version is limited, so read the notice above the tool.
Full walkthrough: Scanned PDF vs Text PDF: How OCR Works and When You Need It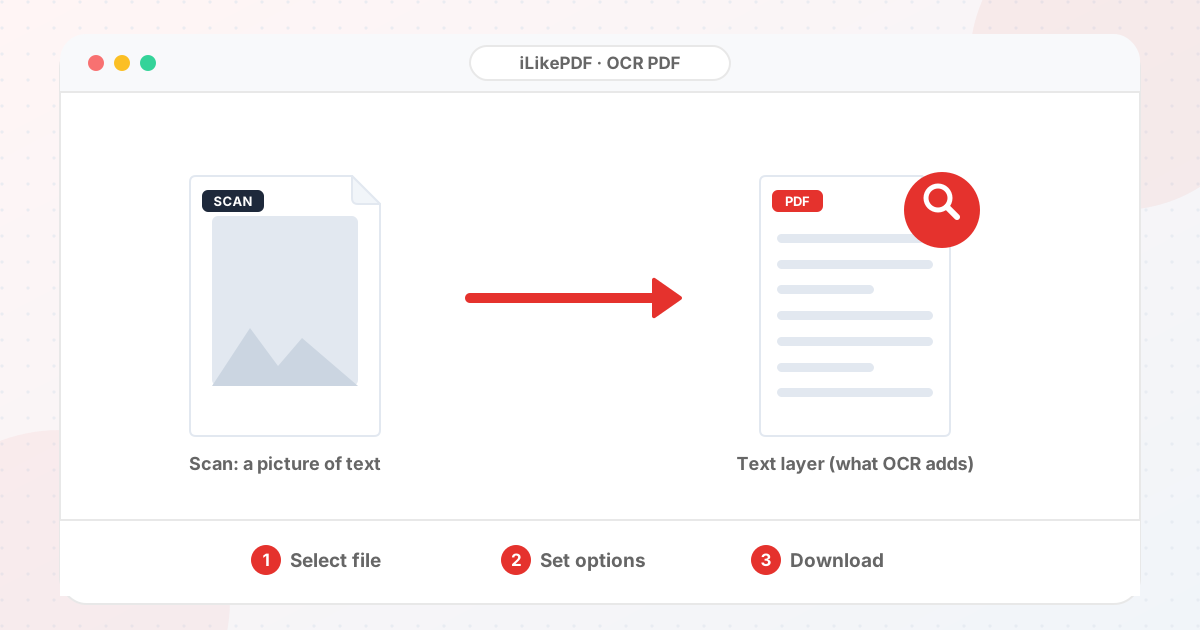
How to Use OCR PDF
- Check whether your PDF already has selectable text: try selecting a word or searching in a viewer.
- If it is a scan, use a desktop OCR application or your scanner's software to add a text layer.
- Verify the result by searching for a word that appears in the scan.
Before & After
Before (Your original file(s))
- Files as you have them
- Nothing has been changed yet
After (New result file)
- A new file downloads to your device
- Your original stays untouched
Conceptual illustration, not a screenshot.
Supported Input and Output
| Accepted input | One PDF (.pdf). | ||||||||||||||||||||||||
| Output | A PDF named ocr_| Text recognition | Not applied in this version. The file is re-saved without a recognised-text layer, so scanned pages do not become searchable. | File handling | The processing code runs in your browser. The page loads the pdf-lib library from the unpkg CDN when it opens; the tool code does not send your PDF to a server. | OCR PDF Features
Who Should Use OCR PDF?
Use Cases and Output ChecksCommon uses
Check the output
Limitations and Troubleshooting
Common problems
Related Tools and GuidesQuick Summary
Share This ToolIf you found this tool useful, share it with friends and classmates: DisclaimerOCR PDF is for personal and educational use. Check your local laws and your organisation's rules before you process copyrighted or sensitive documents. Results depend on your file and browser, so always check the output before you use it. This version of the tool is limited; see the notice above the tool. FAQs – OCR PDF1. OCR PDF kaise use karein?Apni file select karein, settings check karein aur “Run OCR & Extract Searchable PDF” button dabayein. Result neeche dikhega; phir Download par tap karein. 2. Kya OCR PDF free hai?Haan, iLikePDF ka OCR PDF tool bilkul free hai. Koi payment ya signup nahi chahiye. 3. Kya main mobile se OCR PDF use kar sakta hoon?Haan, yeh tool mobile-friendly hai. Aap Android ya iPhone ke browser se bhi OCR PDF use kar sakte hain. 4. Kya meri file upload hoti hai?Nahi. Yeh tool aapke browser me chalta hai; aapki file iLikePDF ke server par upload nahi hoti. (Kuch features ek helper library CDN se load karte hain, lekin aapki file unme nahi jaati.) 5. What does OCR PDF do?OCR PDF recognizes text from scanned document pages. Use it when the required result matches this operation; keep a separate copy of the source. 6. How do I use OCR PDF online?Select the scanned PDF, set any available language options, run recognition and inspect the export. Open the downloaded result before sending it to someone else. 7. Which source should I prepare for OCR PDF?Prepare clear scans with upright text and identify the document language. Start with a file that opens correctly in its usual viewer. A renamed extension does not convert the underlying format. 8. What should I check in the OCR PDF output?Compare names, amounts, punctuation, reading order and search results with the scan. Keep the original until the result has passed these checks. 9. How is OCR different from ordinary PDF text extraction?Text extraction reads existing text objects. OCR attempts to recognize characters in page images, so it can introduce recognition errors. 10. Can OCR read handwriting?Handwriting recognition varies greatly and may be unsupported. Test a representative page and manually verify any important result. 11. Will OCR preserve the exact layout?Not necessarily. A text export may lose layout, while a searchable PDF may place text behind the page image. Check the actual output format. 12. Why does OCR confuse 0 with O or 1 with l?Similar character shapes and low-resolution scans can cause ambiguity. Correct important identifiers manually using the original as the reference. 13. Can OCR recognize Hindi or other languages?Only languages available in the recognition engine are supported. Choose the correct language when possible and test mixed-script pages carefully. 14. Should I compress scans before OCR?Avoid aggressive compression that removes character detail. Keep a good source for recognition and optimize the reviewed result afterward if needed. 15. Does OCR translate the document?No. Recognition converts visible characters into text; translation changes language and is a separate operation. 16. Why is the reading order wrong?Multi-column layouts, tables and rotated text can confuse recognition order. Review the exported text before using it for accessibility or data extraction. 17. Why might OCR PDF fail on a large file?Recognition can be slow on long documents and depends heavily on scan quality. Close unnecessary tabs and test a smaller non-confidential sample to separate a file-specific problem from a browser problem. 18. When is OCR PDF useful?Make scanned notes easier to search or extract words from a paper document. Confirm the recipient’s requirements before preparing the final version. 19. What can I do after using OCR PDF?Related next steps include Split PDF, PDF to Excel, Compress PDF. Choose one only when you need that additional operation. Review the recognized text or a searchable PDF, depending on supported output before applying another change, and retain your source copy. |